
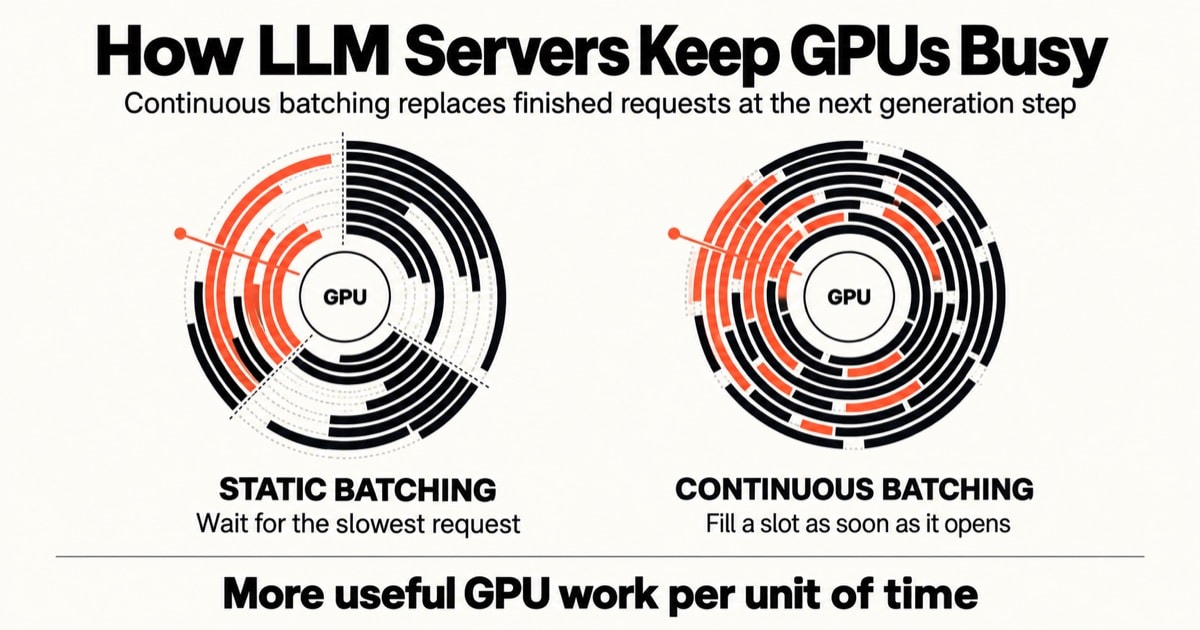
A plain-English guide to continuous batching, why it helps LLM servers use GPU capacity, and how throughput, latency, and memory constraints interact.
Why does an AI take longer to start than to keep generating? Learn how prefill, queues, caching and serving design affect TTFT.
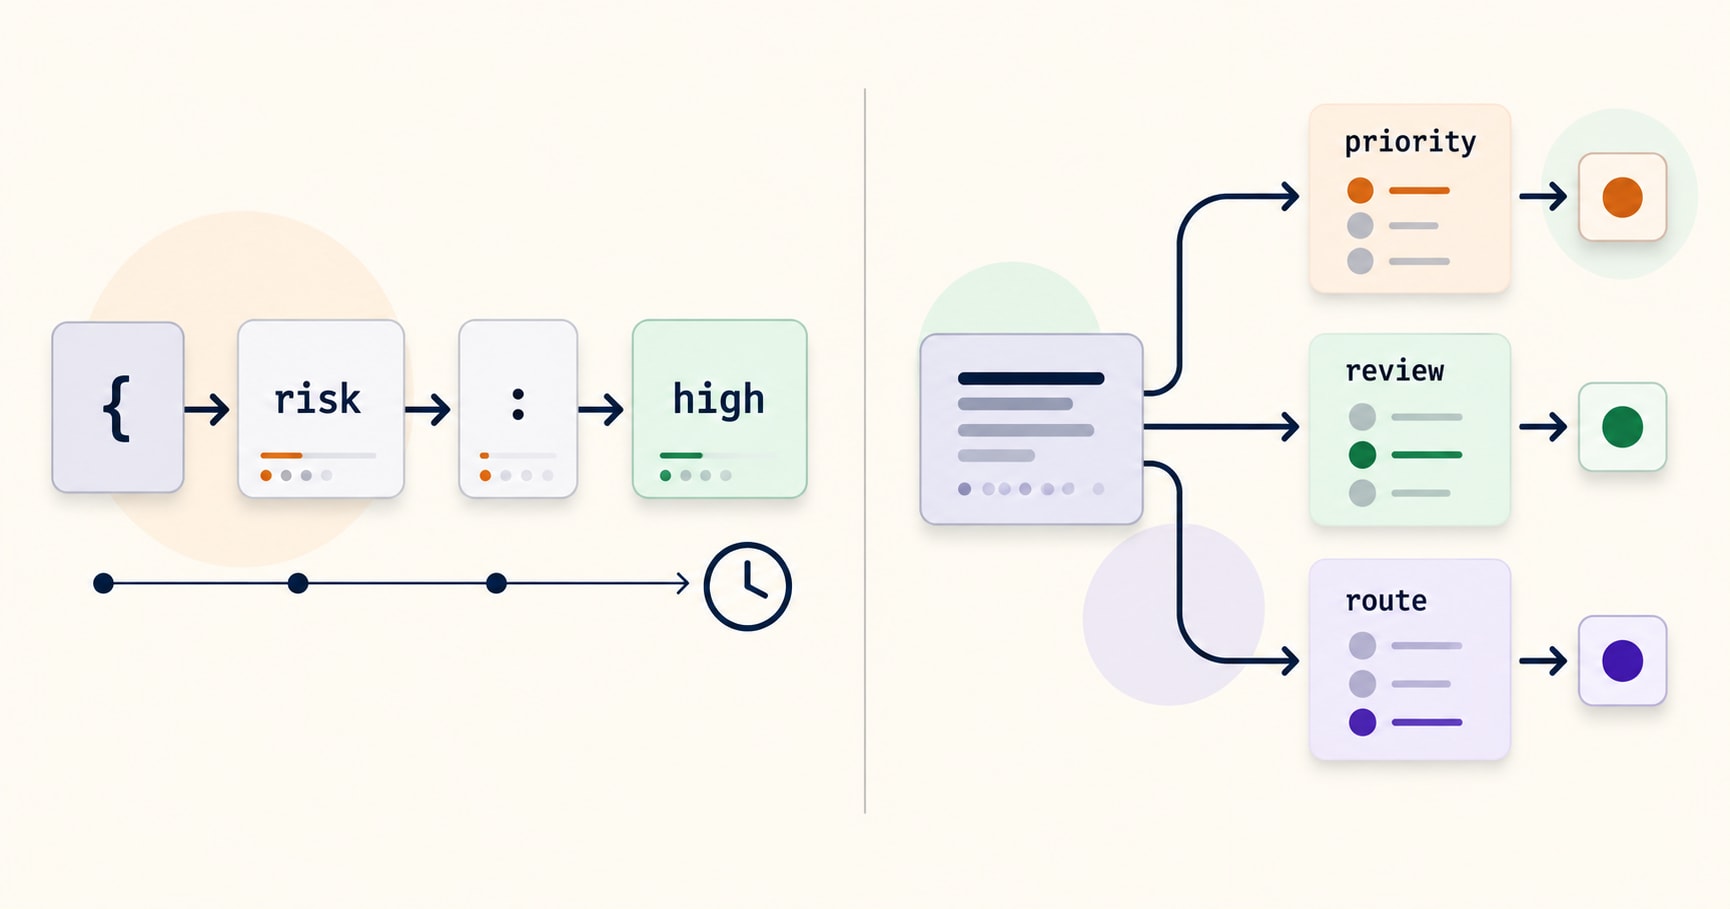
Quick summary Typed decisions: Jev evaluates declared questions in parallel and returns bounded answers instead of generating a JSON string token by token. Keep questions narrow: Define one judgement per field and let application code combine the results. Validate on your own data: Type safety does not guarantee correctness; test accuracy, confidence and review thresholds […]
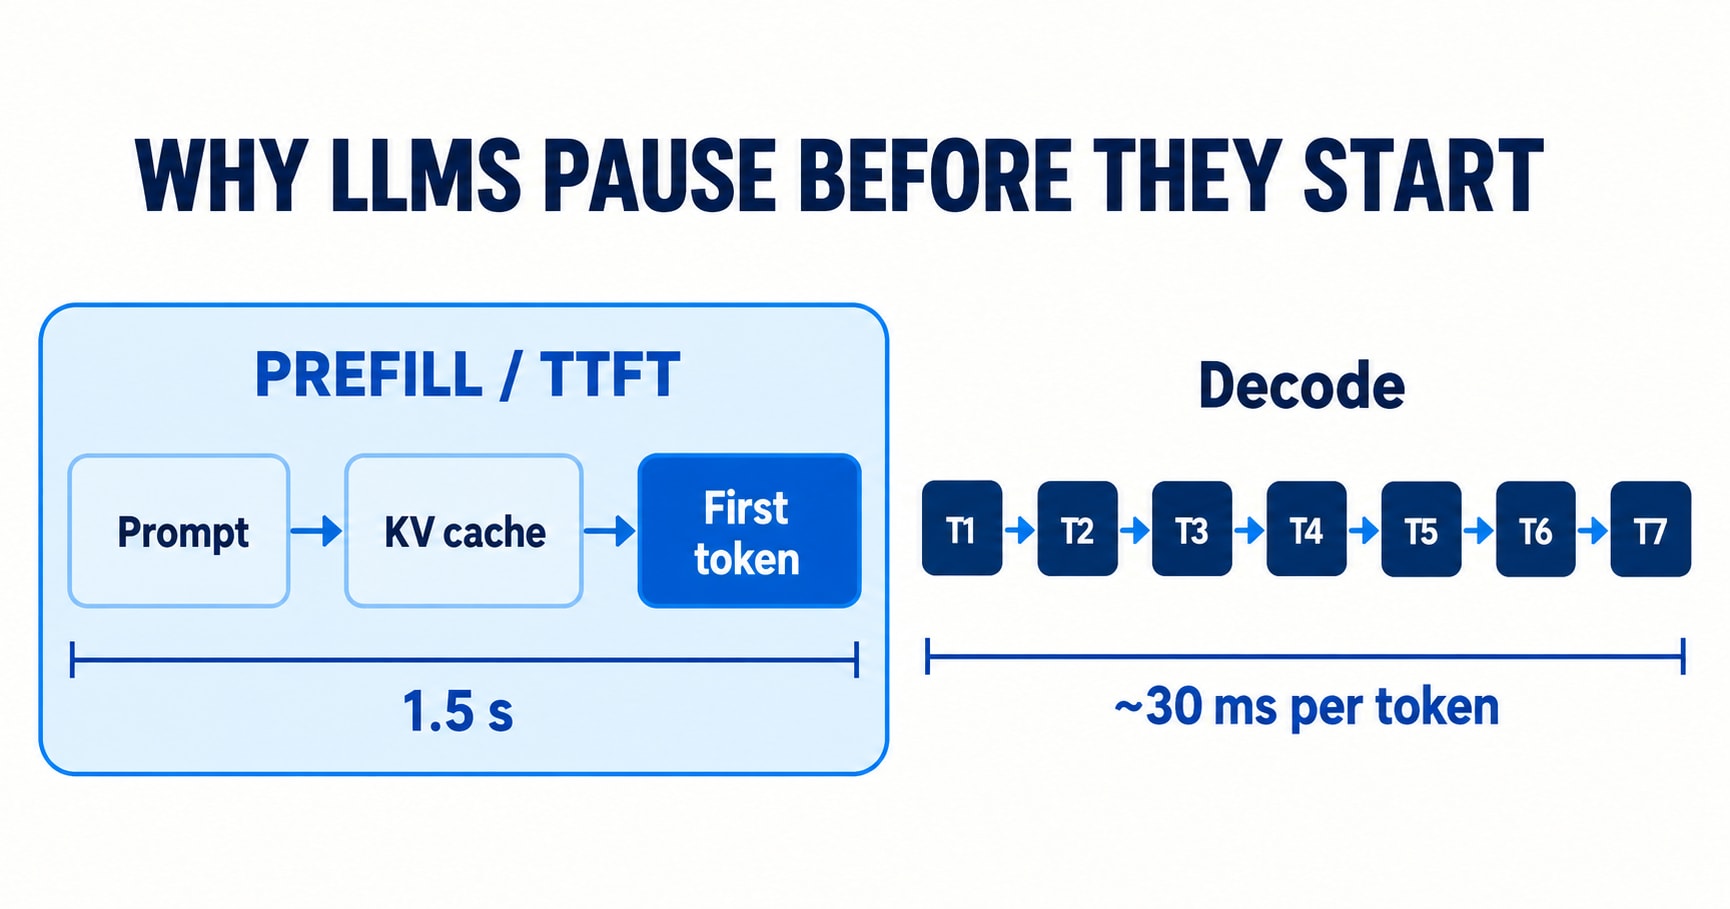
Quick summary Separate latency measures: first-token delay differs from later token cadence and total time. Inspect preparation work: retrieval, queueing, prompt processing and networking contribute. Measure the bottleneck: avoid treating every delay as model slowness. Reduce avoidable work: bound retrieval, reuse stable prefixes and tune serving policy. Time to first token (TTFT) explains a familiar […]