
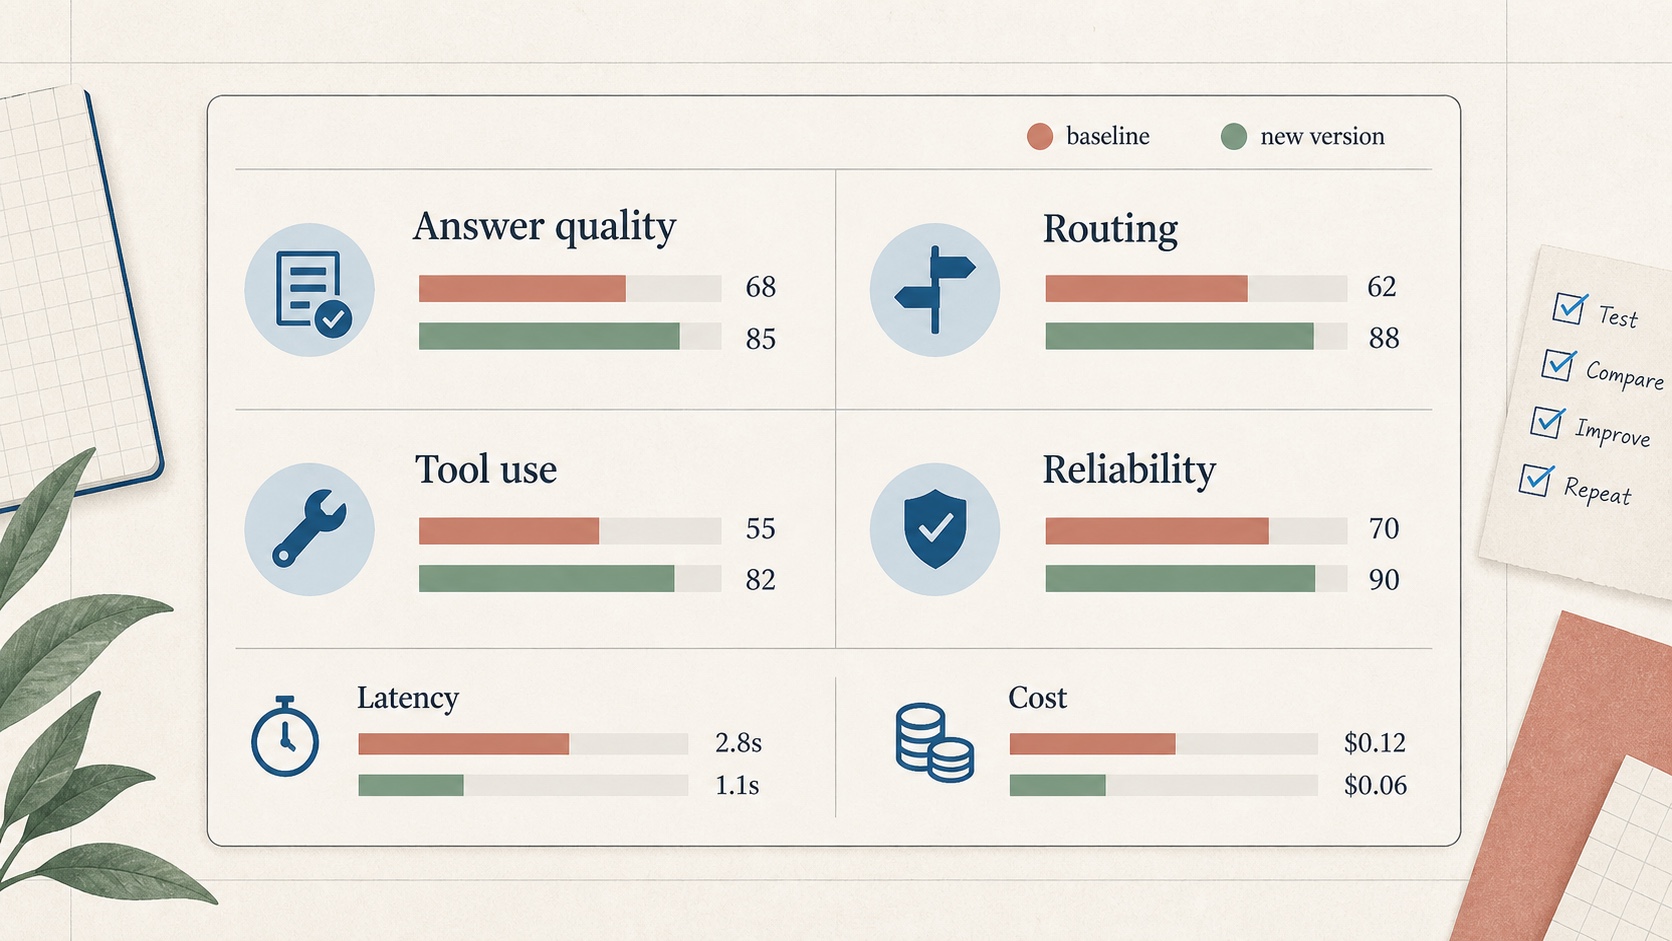
Quick summary Evaluate the whole graph: assess answers, routing, tool use, reliability and cost. Use deliberate test cases: cover ordinary requests, edge cases and safe failures. Compare against a baseline: combine offline tests with production feedback. Apply focused human review: use a consistent rubric where judgement matters. LangGraph evaluation turns a convincing multi-agent demo into […]
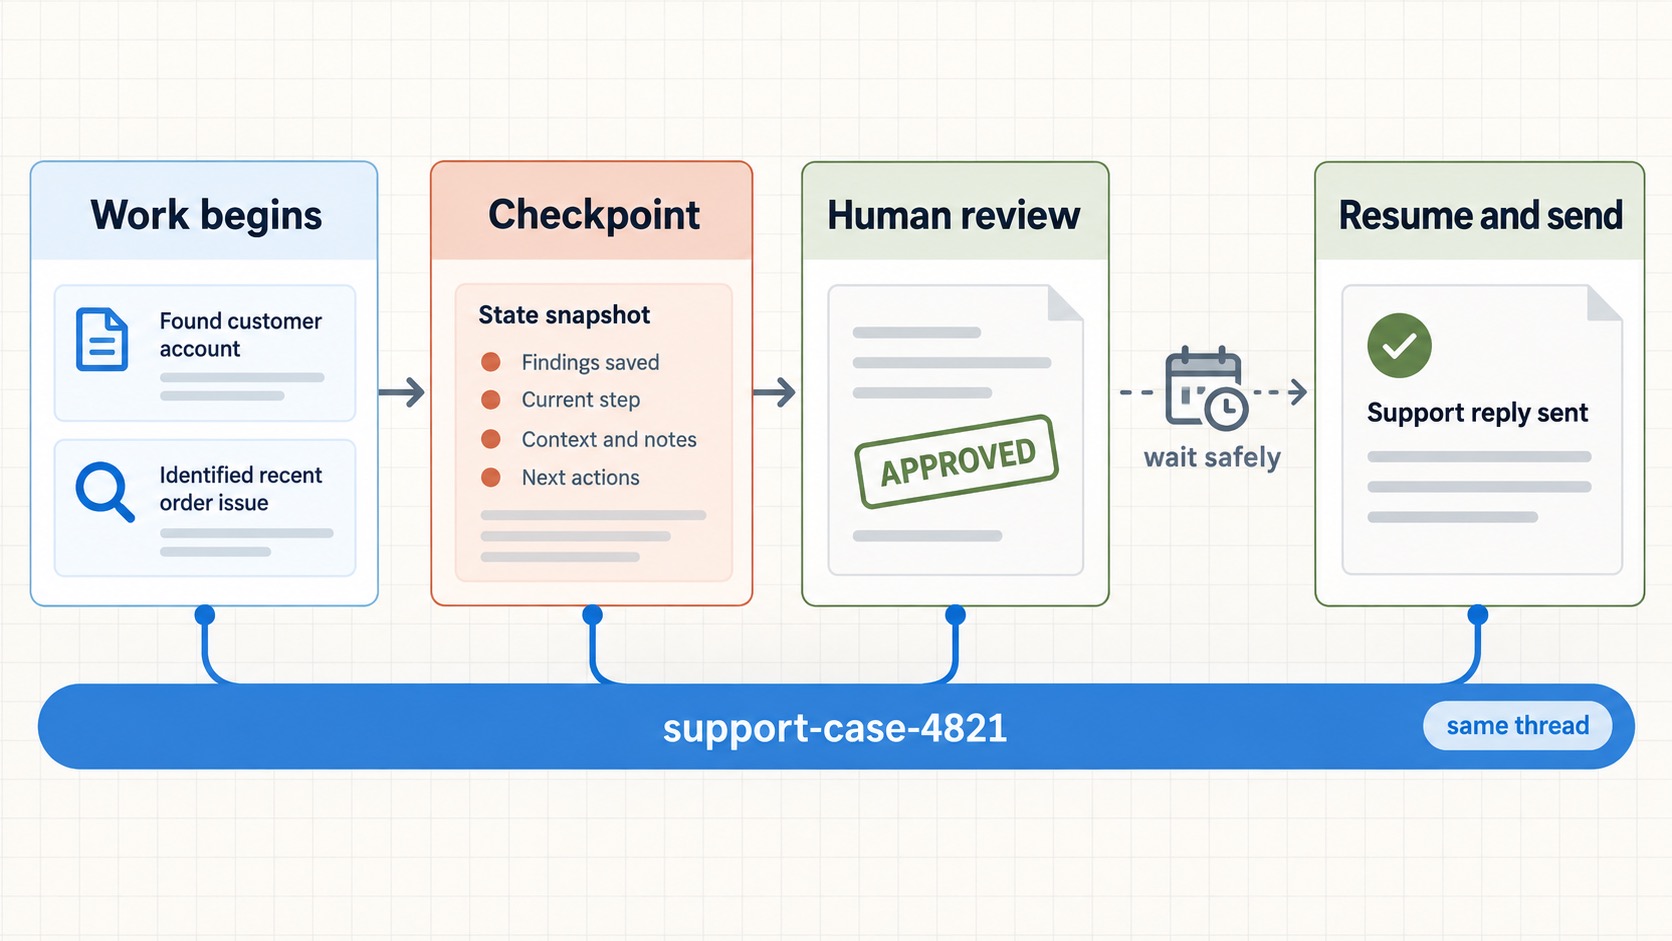
Quick summary Checkpoint state: persistence lets a graph pause, recover and continue. Resume the same thread: reuse its identifier and supply the review decision. Design for replay: repeated execution must not duplicate consequential actions. Use durable storage: production needs an appropriate backend and retention policy. LangGraph persistence is what makes a multi-agent workflow safe to […]
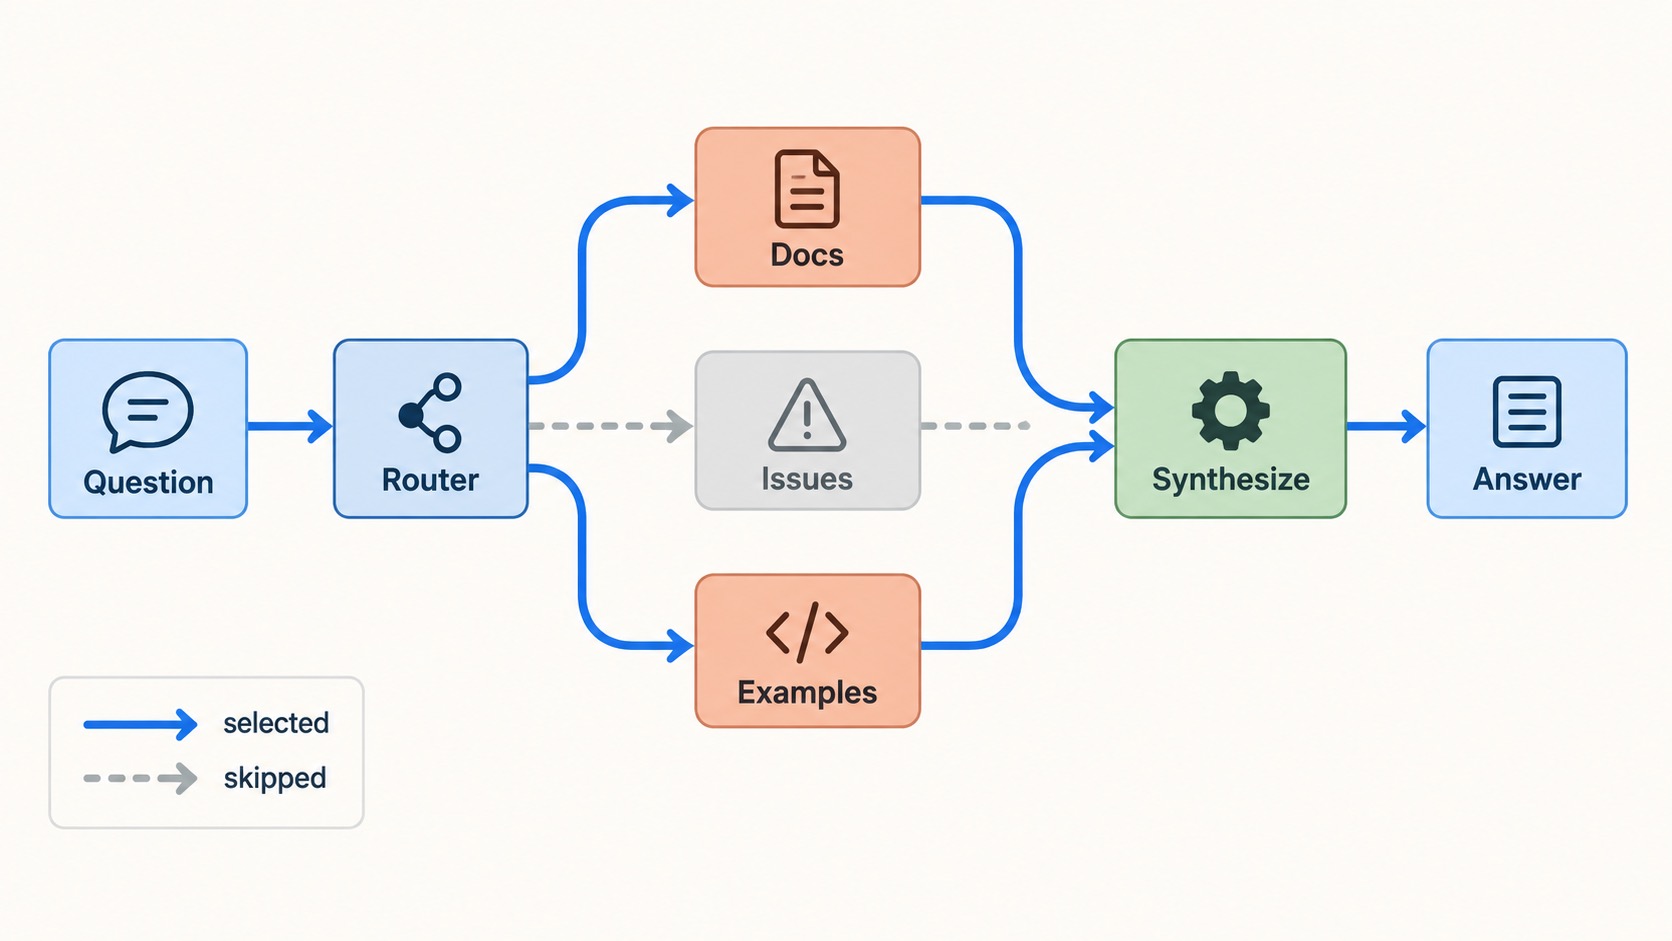
Quick summary Route: inspect the question and select the specialists that can help. Fan out: create one targeted task for each selected worker. Merge: wait for the active branches, then synthesize their findings. LangGraph routing is the point where a multi-agent graph stops broadcasting work and starts making deliberate choices. It decides which specialist should […]
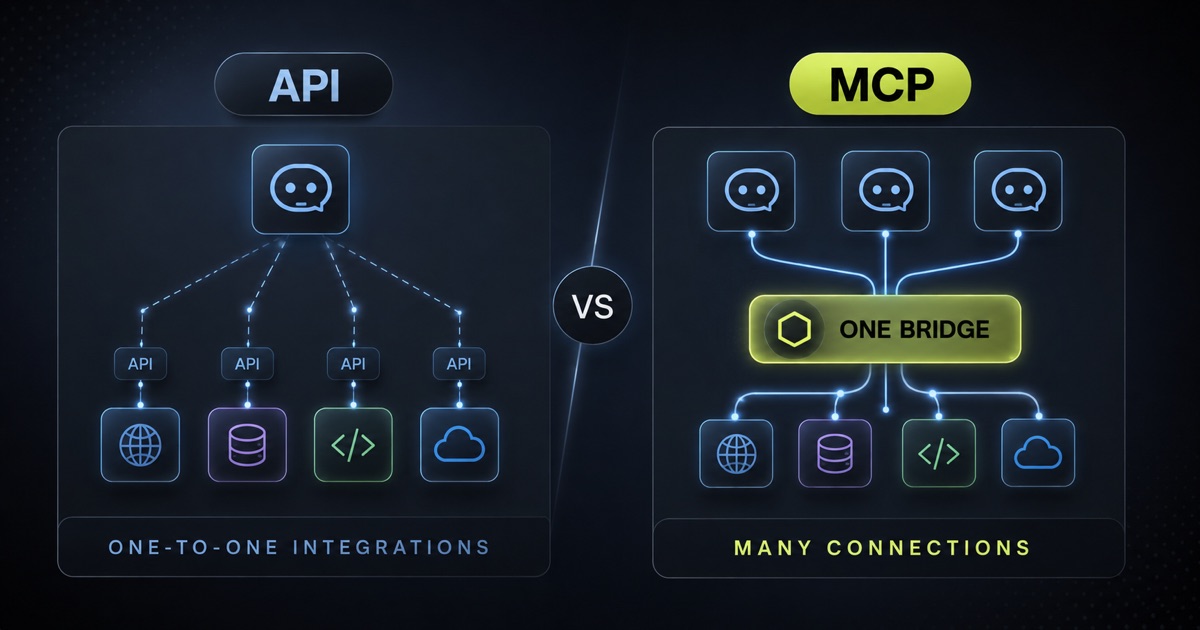
Quick summary APIs expose capabilities: An API defines how software interacts with a system. MCP standardises discovery: AI applications use a common protocol to find and call tools and access context. They work together: MCP often sits above existing APIs rather than replacing them. Choose by workflow: Fixed integrations and assistants that select tools have […]
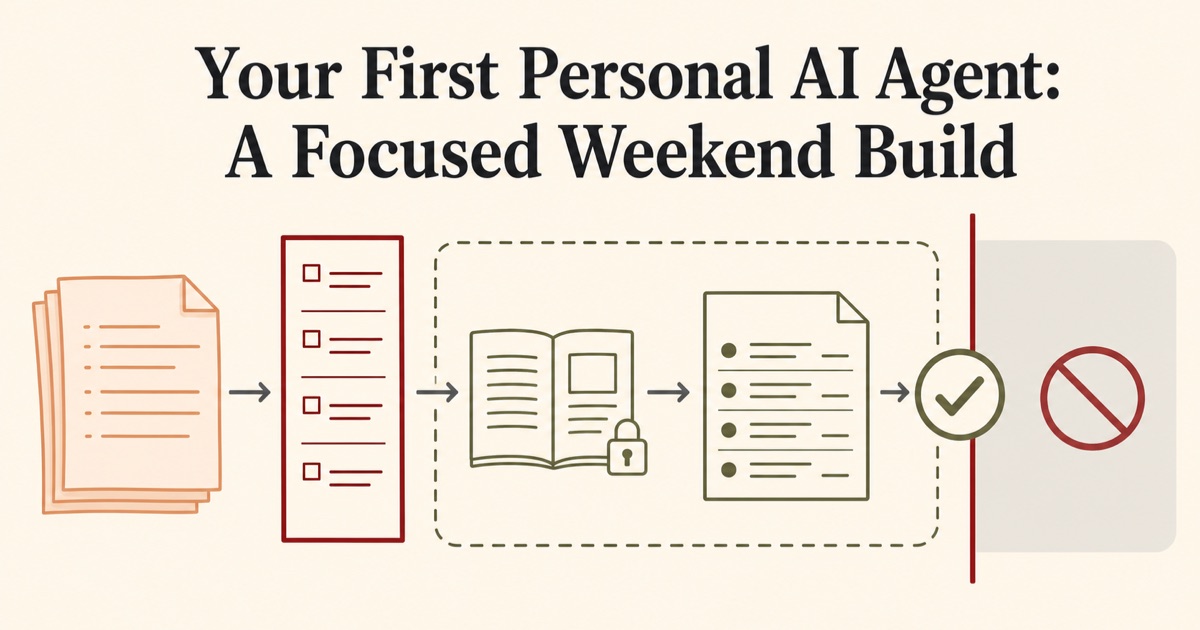
Quick summary Give a personal agent one narrow job, clear inputs, and an output you can inspect. Treat instructions, tools, guardrails, and remembered context as separate choices. Begin with read-only access and require human approval before an external action. Test representative examples before expanding the workflow. The fastest way to get value from a personal […]
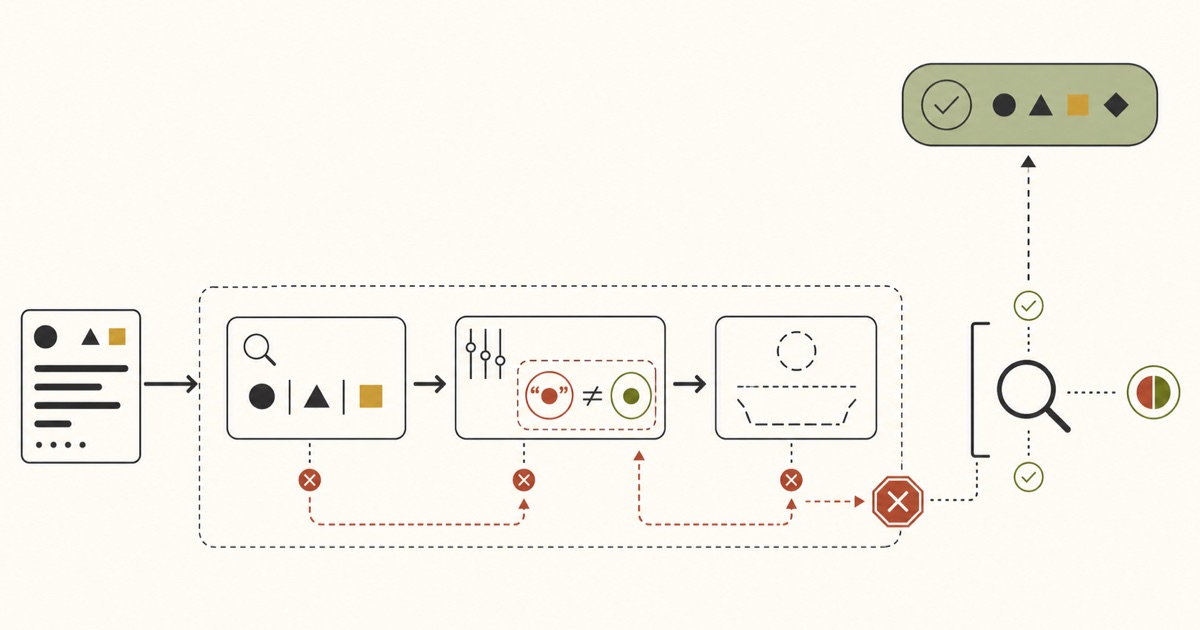
Quick summary A correct final response does not prove that an autonomous agent used the right tools or completed the requested action. Trajectory evaluation scores observable execution steps, including tool calls, outputs, retries, and state transitions. Agent task success and tool use quality expose different failure modes, so evaluate them separately. Start with one important […]