
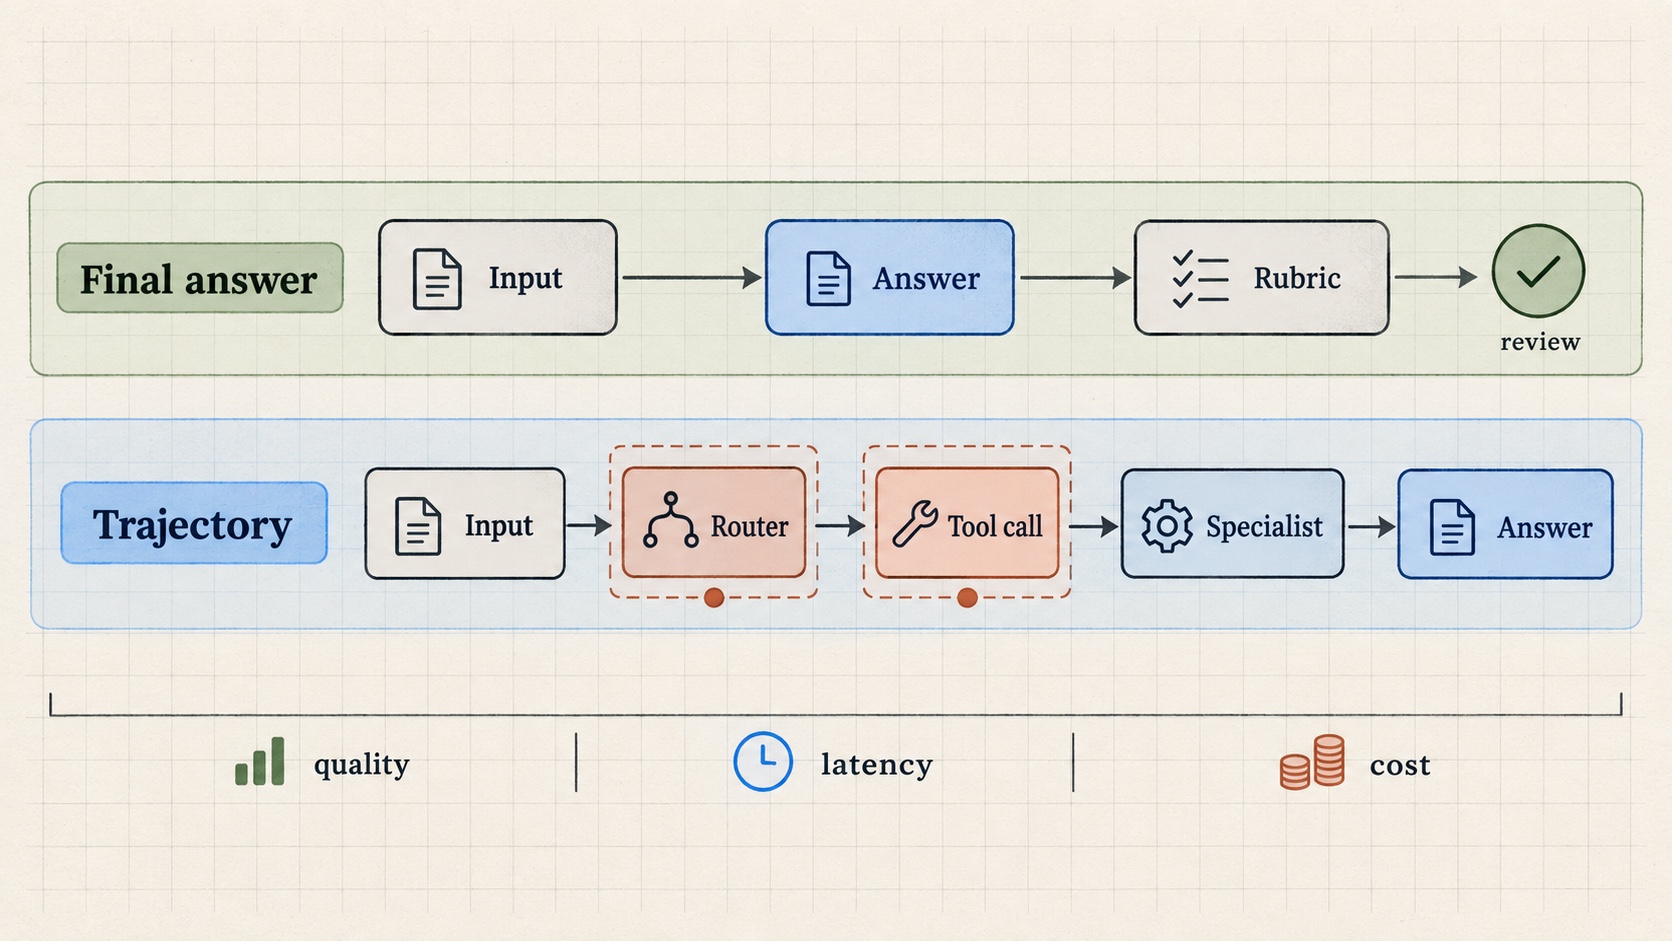
LangGraph evaluation turns a convincing multi-agent demo into a workflow you can improve with evidence. A system may return a plausible answer while choosing the wrong specialist, calling unnecessary tools, or becoming too slow and expensive for real users. This tutorial shows how to measure those failures before they reach production. In the previous lessons, […]
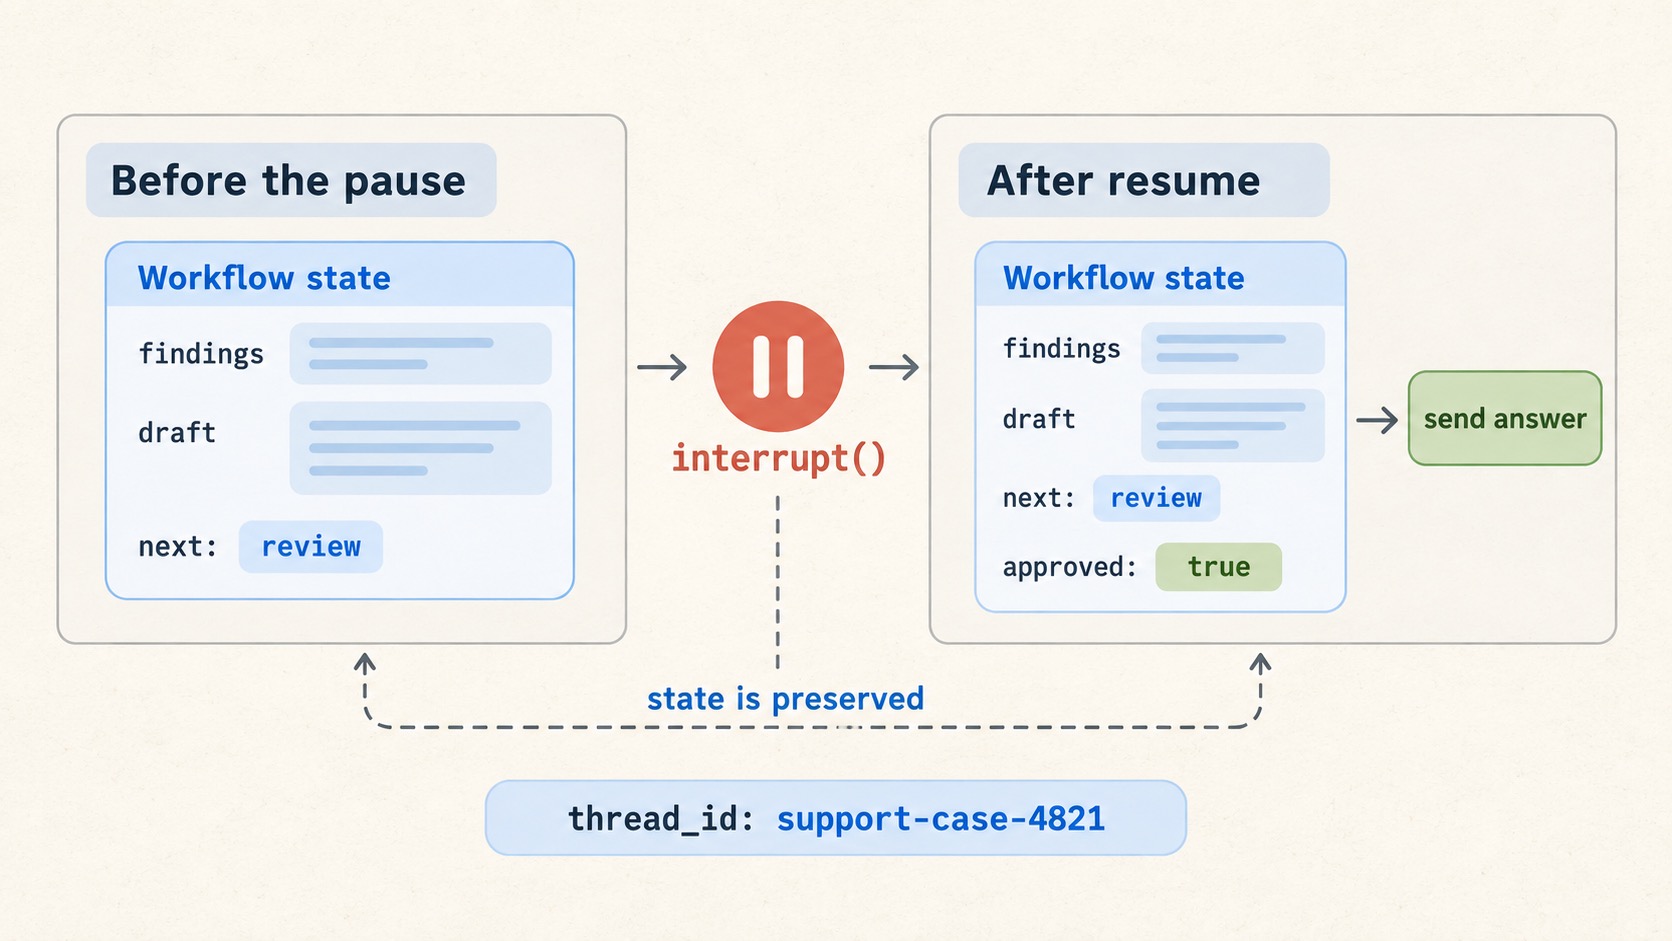
LangGraph persistence is what makes a multi-agent workflow safe to pause, inspect, and continue later. Without it, a process restart, a human review step, or a temporary failure can mean starting the whole graph again—and possibly repeating work that already happened. In the previous tutorial on routing and parallel execution, a router selected specialist agents […]
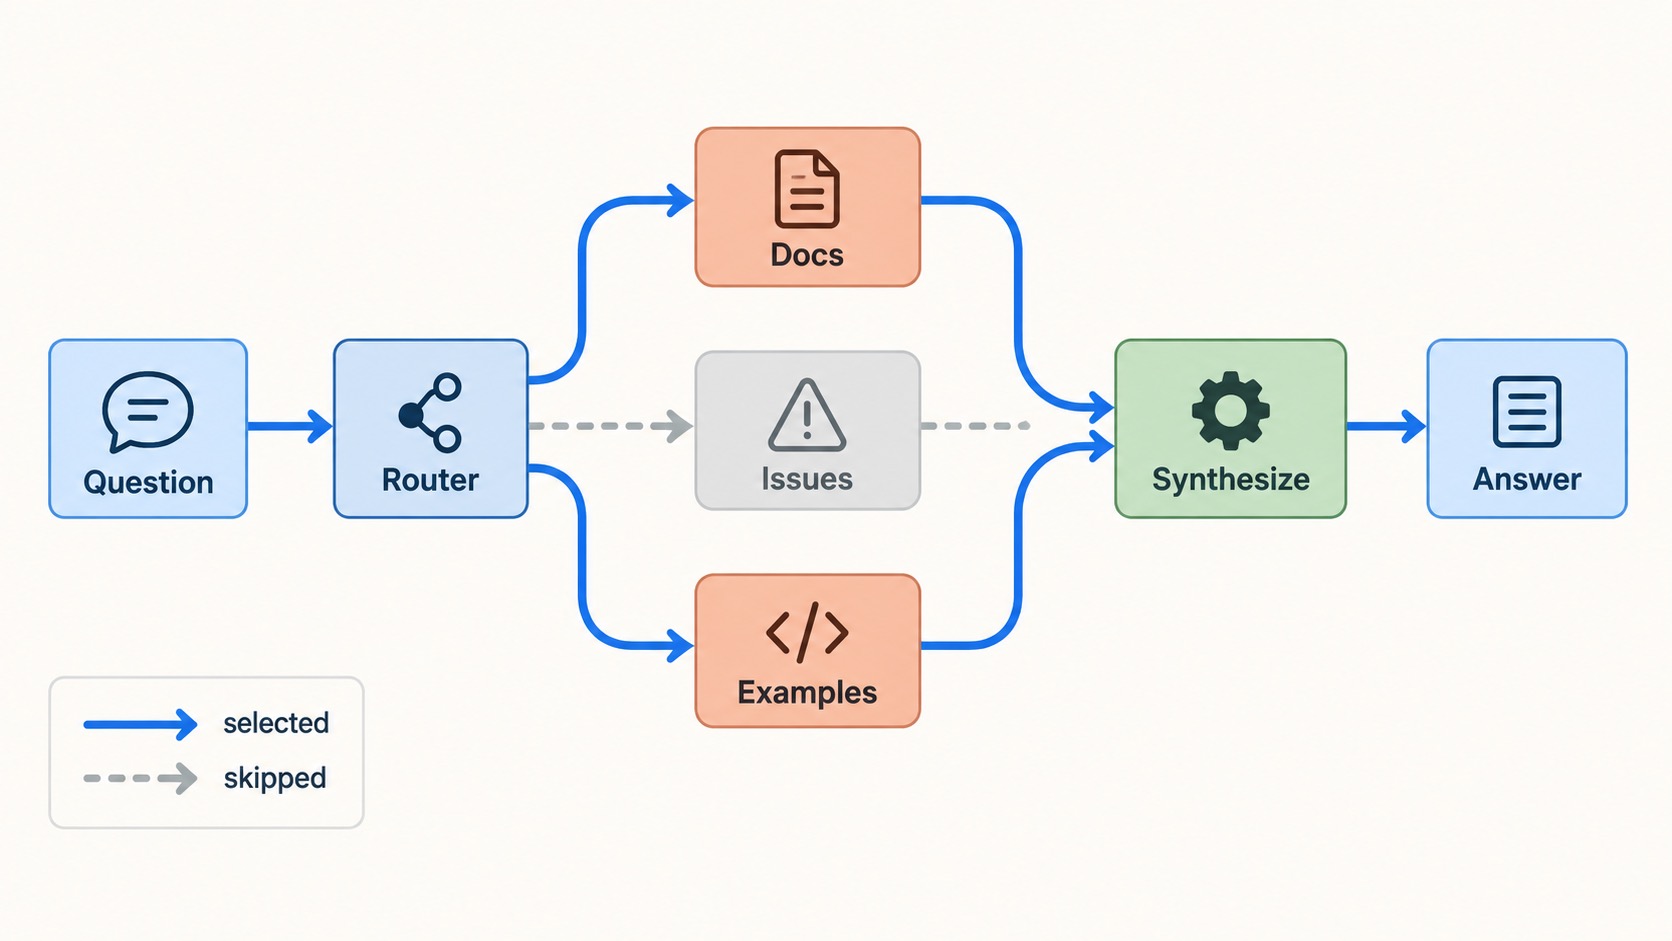
LangGraph routing is the point where a multi-agent graph stops broadcasting work and starts making deliberate choices. It decides which specialist should handle a request, which tasks can run at the same time, and when their findings are ready to combine. In the previous tutorial on LangGraph shared state, we defined safe information flow. Here, […]
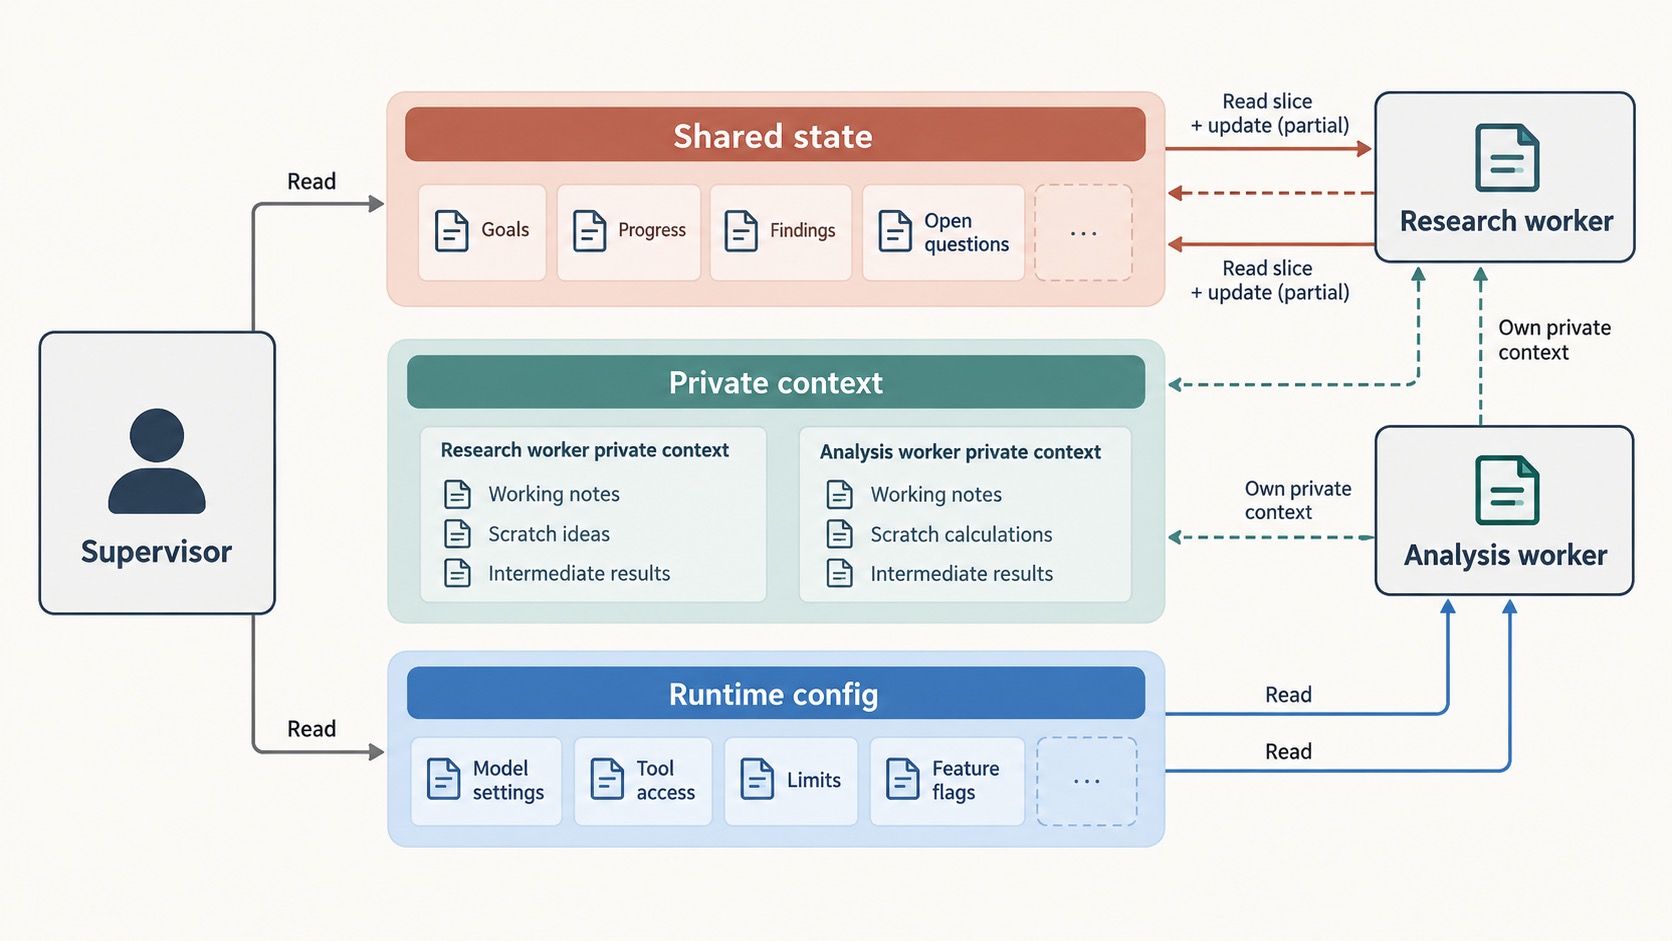
LangGraph shared state is where a multi-agent workflow becomes predictable. A supervisor can choose the right specialist and still produce a weak answer if every worker receives the same noisy conversation history. The next step is deciding what each agent can read, what it may return, and what must remain private. This tutorial continues the […]
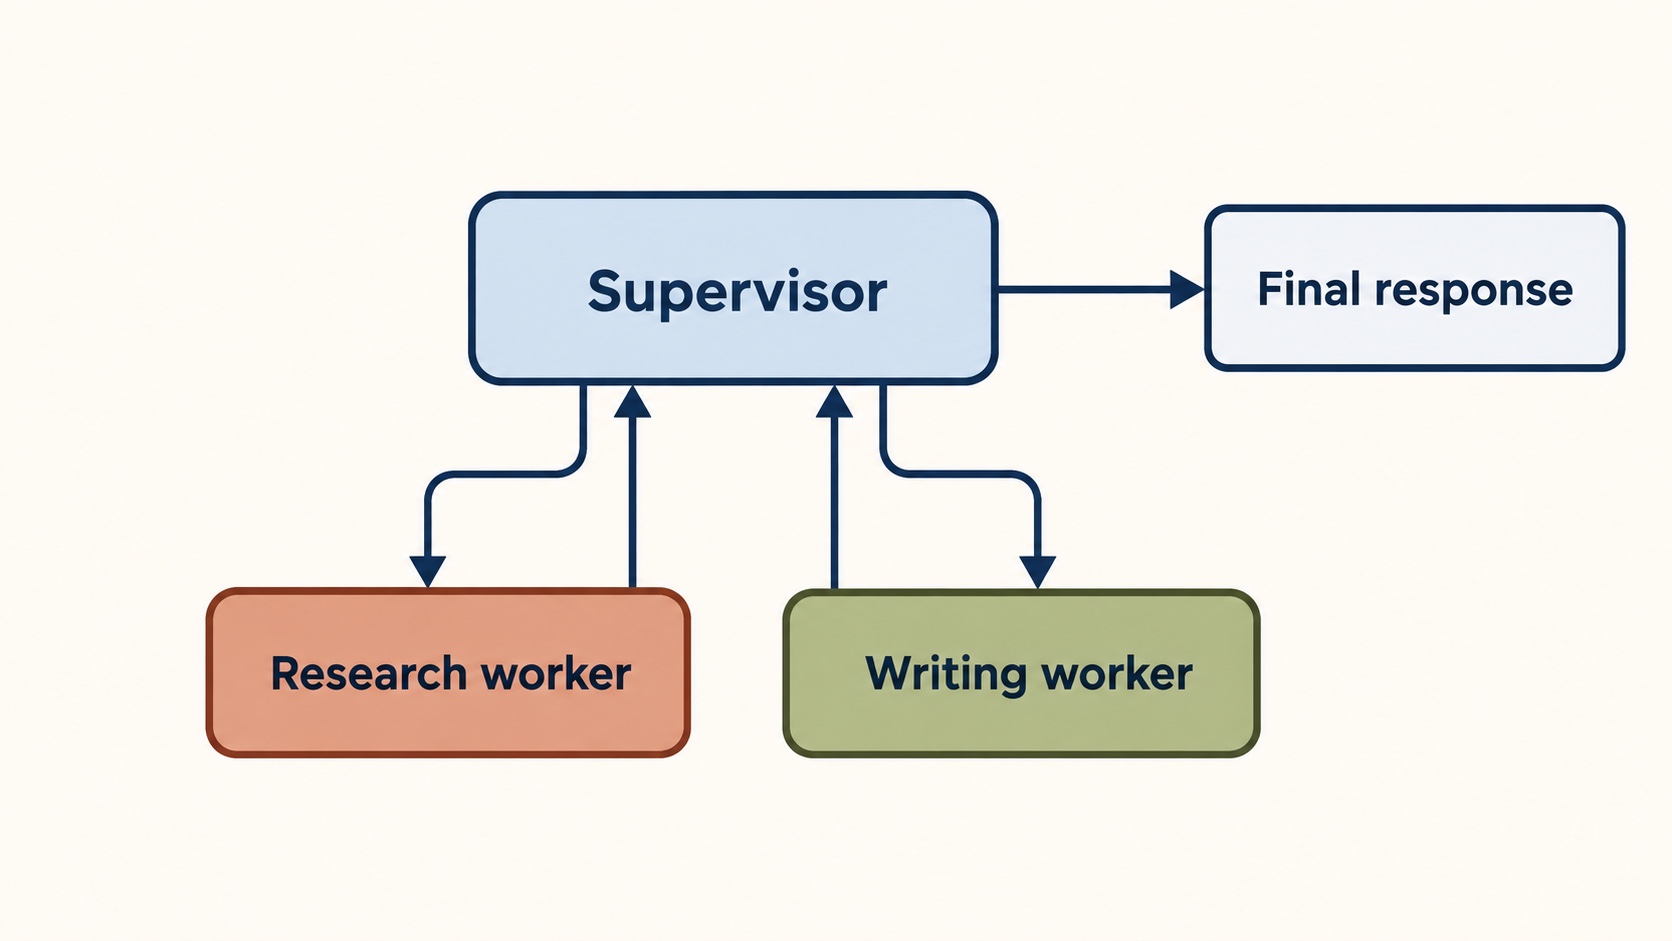
LangGraph Supervisor Tutorial · Multi-Agent SystemsPart 2 of 6 · View the series guide ← Part 1: Build a conversational agent with LangGraph A LangGraph supervisor tutorial should begin with a simple idea: a useful multi-agent system is not a group of bots talking at random. It is a workflow with a clear decision-maker. One […]
GPT-6 Astra has not broken the rules of AI system design. It has made the limits of those rules much harder to ignore. OpenAI’s new model is built for work that stretches across browsers, files, code, research, and professional software. It can plan, use tools, inspect results, adapt to new instructions, and continue through a […]
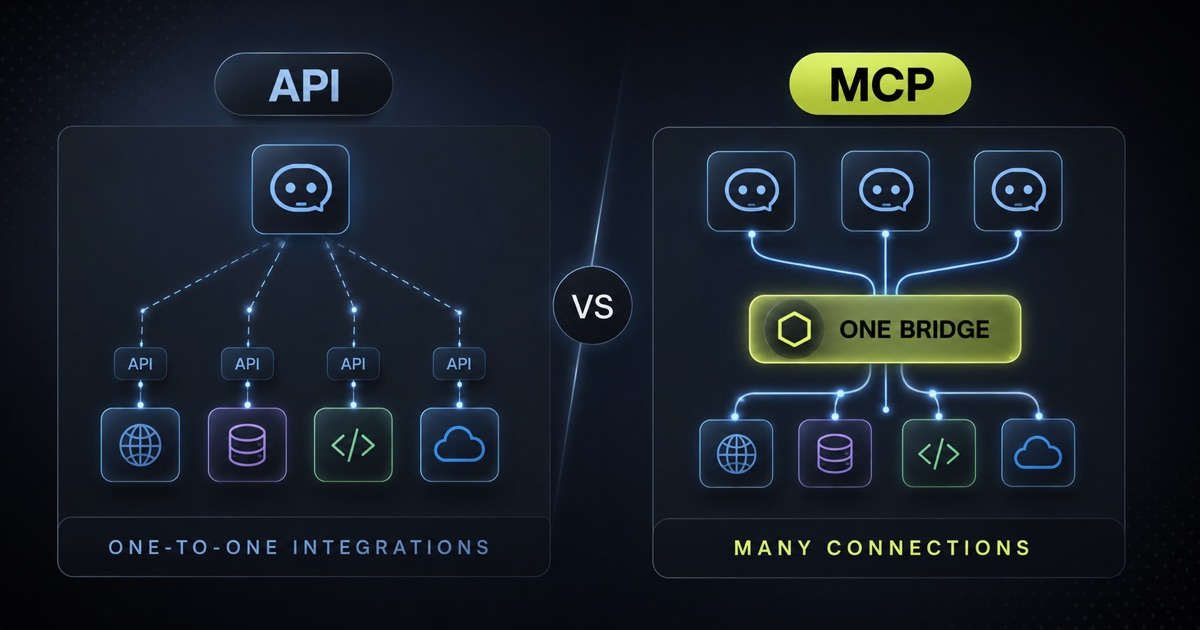
If you are comparing MCP vs API, the short answer is that they solve different integration problems. APIs expose capabilities; MCP gives AI applications a standard way to discover and use tools and context. Key takeaway: An API is a contract for interacting with a system. MCP is a protocol that helps AI applications discover […]

Ninety four thousand block reads for one row, by its UUID primary key. I read that line three times, half convinced I had pasted the wrong output into my own terminal. That query used to come back in under 20 milliseconds. At 200 million rows, it took almost four seconds. The only reason anyone noticed […]
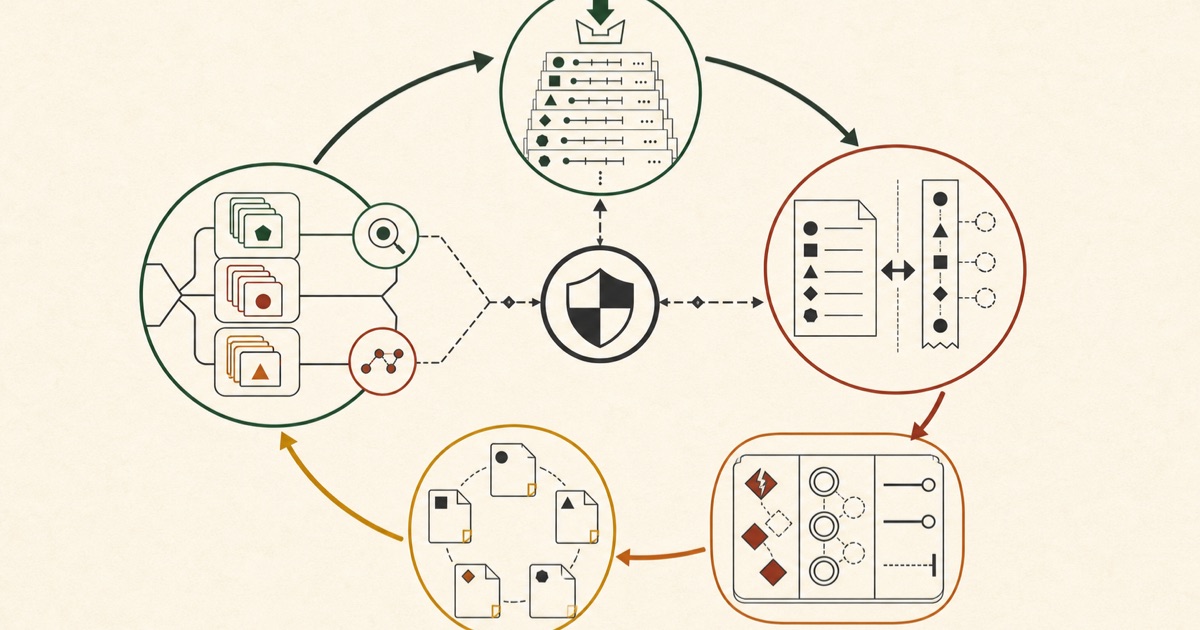
An agent evaluation flywheel can expose the path an AI agent took to reach an answer. A final-answer score can hide wrong tools, needless retries, weak evidence, or a failure to adapt when new information appears. That creates a practical question: what should change next? This post turns that diagnosis into a five-stage operating model. […]

Trajectory evaluation shows how a final answer can look perfect while the agent behind it has already failed. Imagine an agent that tells a support team: “The customer record has been updated.” The sentence is clear and reassuring. However, the trace may show a different story. It may select a search tool instead of an […]
If by “turbo vec” you mean the project source, it is a project aimed at a familiar AI-infrastructure problem: storing and searching embedding vectors without treating memory, storage, and retrieval quality as afterthoughts. Its repository describes TurboVec as a vector index built on TurboQuant, written in Rust, with Python bindings. That description is useful, but […]

This multi-agent workflow roadmap introduces coordinated AI roles and workflows working toward one outcome—not magical, fully autonomous AI teams. It is the starting point for the series, and it will become a linked learning path as each tutorial is published. Key takeaways A multi-agent system divides a broader job among defined AI roles and workflow […]

A feature request looks small until it crosses every layer of an application. Clean Architecture with SOLID helps when a checkout rule touches an HTTP handler, ORM model, pricing calculation, email notification and message consumer at once. It separates the business decision from the machinery used to deliver and store it. Clean Architecture is not […]

When you type claude into your terminal, there is a highly sophisticated Claude Code boot sequence that springs into action before you even see the first prompt. By understanding this pipeline, developers can better reason about startup latency, debug initial launch behaviors, and appreciate the careful parallelism engineered to keep time-to-interactive incredibly low. (Looking to explore more AI tools? […]

Context engineering for AI agents becomes essential when a promising demo meets a real workflow. After a few turns, an agent may repeat a question, follow an outdated instruction from the chat history, or spend most of its prompt on tool logs that do not affect the next decision. The answer is not to carry […]