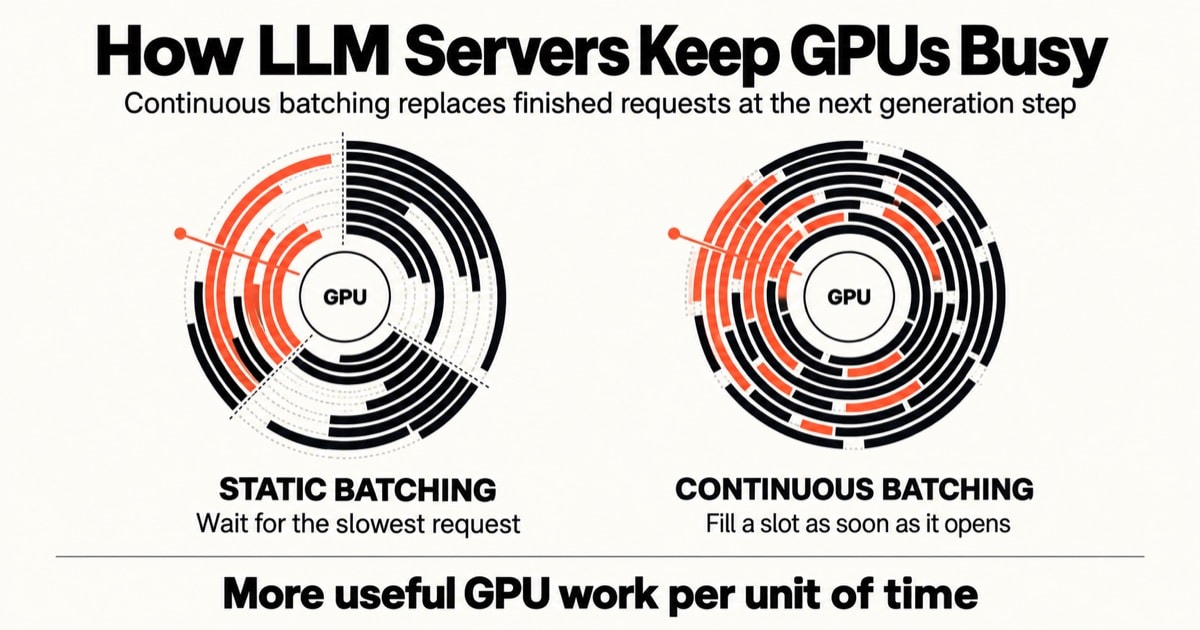
A plain-English guide to continuous batching, why it helps LLM servers use GPU capacity, and how throughput, latency, and memory constraints interact.

A plain-English guide to continuous batching, why it helps LLM servers use GPU capacity, and how throughput, latency, and memory constraints interact.