
How Continuous Batching Keeps LLM Servers Busy While You Wait
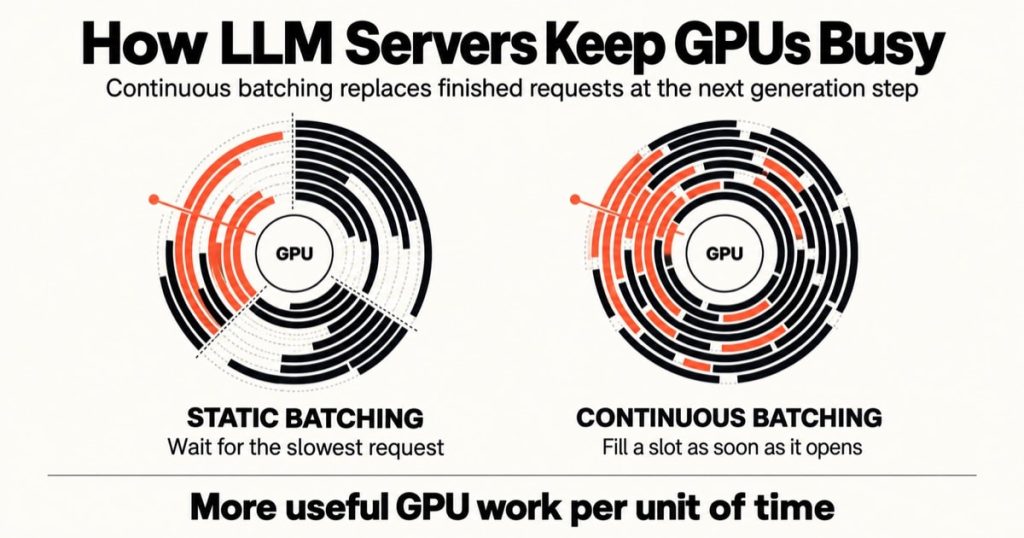
Quick summary: Continuous batching
- Requests finish at different times: A fixed batch can leave GPU capacity idle while its longest response continues.
- Continuous batching refills slots: The scheduler can admit waiting requests at generation-step boundaries as other requests complete.
- More work can share the GPU: This often improves total throughput, though it does not guarantee lower latency for every user.
- Memory still sets the limit: Active sequences need GPU memory for their growing context, so schedulers balance request count, token work, and KV cache capacity.
When an AI answer arrives a token at a time, one long response can hold up a whole group of shorter ones. That is the scheduling problem behind continuous batching, a technique used by LLM inference servers to keep GPU capacity doing useful work as requests start and finish.
Why fixed batches leave capacity idle
Large language models generate text autoregressively. After the server processes a prompt, the model predicts a token, then uses that token to predict the next one. In the decode phase, each active request usually needs another model step to produce another token.
With static batching, a server collects several requests and runs them as one batch until every request is done. If one response needs 900 tokens and another needs 150, the shorter one may finish much earlier but the batch can remain tied to the longer request. New arrivals wait for the batch to drain before they can join.
This is a little like a shuttle that waits for every passenger to finish a long trip before it picks up anyone else. The GPU has work to do for the remaining requests, but some of the available batch capacity may sit unused.
How continuous batching changes the schedule
Continuous batching makes the scheduling decision repeatedly, around the model’s generation steps, instead of locking the full request group together for its entire lifetime. When a request reaches its stopping condition, the server can remove it from the active set. It may then admit a waiting request into the freed capacity for a later step.
In the shuttle analogy, each passenger gets off independently and someone waiting can board at the next stop. The shuttle stays in service instead of returning only after the slowest journey ends.
The foundational Orca paper describes this as iteration-level scheduling: the system schedules one model iteration at a time. Modern serving engines build on related ideas, while adding their own scheduling policies, memory management, and execution optimizations. The core benefit is straightforward: completed work does not need to keep a slot occupied until unrelated requests finish.
What happens inside a serving engine
A request typically moves through two broad phases. During prefill, the model reads the input prompt and builds the state needed to continue it. During decode, it generates output token by token. The scheduler chooses work for each execution step, and not every step has to contain exactly the same requests or amount of token work.
Each active request also uses a KV cache, which stores attention data from its prompt and generated tokens so the model does not have to recompute the entire history every time. As a response grows, its cache takes more GPU memory. If memory or compute limits are reached, a server may have to delay admission, pause or pre-empt work, or otherwise adjust its schedule. Continuous batching keeps the queue flexible; it does not make GPU memory unlimited.
In vLLM, for example, max_num_seqs limits how many sequences can be processed in an iteration, while max_num_batched_tokens limits the token work scheduled in that iteration. These settings describe different capacity constraints, and their useful values depend on the model, GPU memory, prompt lengths, and workload. See the vLLM scheduler configuration for the current definitions.
What continuous batching improves, and what may not
The main expected gain is throughput: more requests or output tokens completed over a period of time, especially when many requests are arriving and have different lengths. Keeping active work packed more efficiently can also improve hardware utilization.
That does not mean every individual response becomes faster. Under load, admitting more sequences can increase contention for compute and memory bandwidth. A request may wait in a queue before it starts, and the time between its output tokens can change as the batch changes. If you’re comparing systems, measure time to first token, inter-token latency, and total completion time alongside throughput. Our guide to time to first token explains why the first visible response delay is a separate part of the experience.
So the practical trade-off is between serving more concurrent work and maintaining the latency targets users care about. Operators tune the scheduler and workload limits against measured traffic rather than assuming that the largest possible batch is always best.
How to read the comparison graphic
The graphic contrasts a fixed group, which waits for its longest request, with a continuously updated batch, which can fill newly available capacity. Its circles are a simplified picture of scheduling slots. They are not a simulator of GPU execution, and they do not predict a particular server’s utilization or request count. Real results depend on prompt and output lengths, request arrival patterns, hardware, model, and configuration.
The durable takeaway is that an LLM server can reconsider who runs at each generation step. That small shift helps prevent finished requests from tying up capacity, while the scheduler continues to respect compute and memory limits.
Further reading
- Orca: A Distributed Serving System for Transformer-Based Generative Models, the OSDI paper on iteration-level scheduling.
- vLLM scheduler configuration, with current sequence and token scheduling limits.
- SGLang documentation, for another open-source LLM serving runtime.